Flüpke
fluepke@chaos.social
Counting the characters in ONE CHARACTER remains an open problem in computer science.

 7
 6
 3

[4FBB09]
5225225@furry.engineer
@fluepke it's very fun to, in rust, have someone ask "how do i do character indexing in a string, string[i] doesn't work" and then get to do the "okay so "character" is not particularly a meaningful term, what are you trying to do?" discussion
(anyways, IMO byte indexing/byte strlen is the most sensible way of doing it, especially if you're using UTF-8)
3
0
2
Flüpke
fluepke@chaos.social* PHP's strrev reverses a string byte-wise, thereby corrupting UTF-8. 🤦
* For Python's encode() UTF-16 is neither UTF-16-LE nor UTF-16-BE. 🤨
* NUL-terminated C-Strings. 💀
* strlen() 👻
Do you know further string processing horrors?
6
0
2
 /Cinny


Another hole in this hole about the string size is the question about how many columns this string needs on your terminal!
1
0
2
[4FBB09]
5225225@furry.engineer
0
0
2


Flüpke
fluepke@chaos.socialComputer scientists be like:
Let Σ = {a, b, c} be an alphabet. A string is an element of Σⁿ. DONE. STRINGS SOLVED. QED. 👏
Engineers meanwhile:
Humanity has spent thousands of years developing hundreds of writing systems and countless ways to express meaning through text. Let's account for that!
Meanwhile, some guy writing C since 1978:
Wait, there's writing beyond ASCII? Sounds like a skill issue. If you need umlauts, you deserve the extra screening at US immigration!
2
0
1
 0
0
0

Dr. Christopher Kunz
christopherkunz@chaos.social@fluepke This is your alarm clock: It's time to exit this rabbit hole and enter the next rabbit hole.
0
0
1

zoe  - 4 arc
commanderred@chaos.social
@fluepke can I interest you in unsigned char based strings? :3
0
0
1

@fluepke isn’t there utf-16-le/be in python to explicitly define the byte order?
1
0
0
Flüpke
fluepke@chaos.social@souliboi yes. If you do not specify endianess, python's encode("utf-16") adds a byte order mark, that is not present when using encode("utf-16-le") or utf-16-be.
I find it kinda funny, that str.encode("utf-16") != str.encode("utf-16-le") != str.encode("utf-16-be")
1
0
0

Bill Ricker
n1vux@mastodon.radioUse of UTF (other than perhaps UTF8) without a BOM is an anti-pattern of assumed context.
If it conforms to LOCALE, that assumption is valid, but only until the octet stream is shared to other LOCALEs.
Collecting up test cases for multiple encodings is worthwhile (i18n good) but a PITA, made worse (2×) by BOM optionality. 🤦♂️🤷♂️
1
0
1

Henryk Plötz
henryk@chaos.social@fluepke In MySQL, when you ask for "utf8" encoding, you don't get UTF-8 encoding. You get "UTF-8, but not beyond U+FFFF".
If you want "UTF-8, like, really" you have to ask for "utf8mb4" encoding.
0
0
1
gudenau
gudenau@hachyderm.ioShow content
@fluepke The state flags explode more, but aren't required. Michigan is a flag start, flag u, flag s, flag m, flag i, flag end which ecodes to f0 9f 8f b4 f3 a0 81 b5 f3 a0 81 b3 f3 a0 81 ad f3 a0 81 a9 f3 a0 81 bf.
Java also uses a modified UTF-8 so they can encode null bytes in the strings without using a null byte.
1
0
1
Flüpke
fluepke@chaos.socialShow content
@gudenau that is absolutely horrifying!! I love it! 💯
I usually overlong utf8-encode NUL characters, when I am about to exploit stuff. Didn't know this exploitation technique is a design pattern to the Java enterprise world. 😅
But what's absolutely killing me, are Java's UTF16 surrogates within """M""-UTF8! 🤣
I guess, the M in MUTF-8 stands for mutilated, right? Right??
0
0
1
ramona (fafo as a service)
ramona@app.wafrn.netwait which language gives string length in grapheme clusters as the default normal string length????
2
0
1

ramona (fafo as a service)
ramona@app.wafrn.net@fluepke@chaos.social @buffet@chaos.social
woah, wild
though at this point i am of the opinion that having a .count/.length/whatever method on a string is a language design mistake and all the methods should explicitly say which length they give (and in case of grapheme cluster allow specifying which kind and in which locale because text is a mess)
2
0
1
Hopeless Noosphere Situation Warrior 

cyberquixote@infosec.exchange
The problem with Computer Science is much of it has pro Capitalism/Colonialism Bias.
Others will disagree, but I think that's a problem. You cannot disagree because consider who built these systems, what do you think the purpose was?
1
0
1
Flüpke
fluepke@chaos.social@cyberquixote @adamshostack @ryanc I do fully agree. ASCII is modern-days colonialism and racism, expressed as code.
Everyone, including Mastodon, should be severely ashamed for only supporting ASCII. There is absolutely no excuse for artificially restricting text input to something that is incapable of Unicode (using whatever encoding).
0
0
1

Alvar Freude
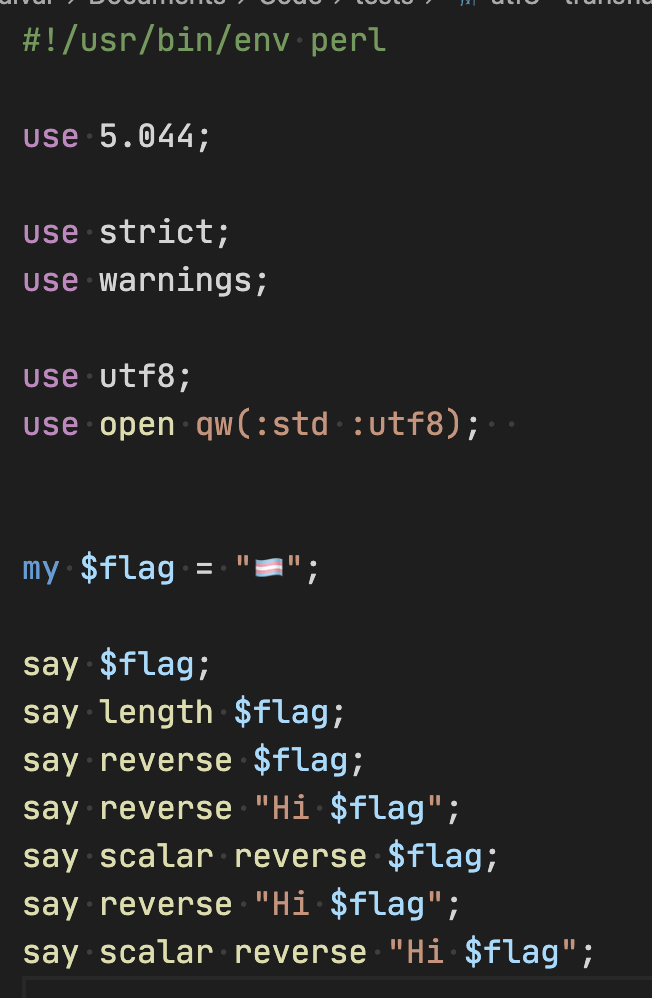
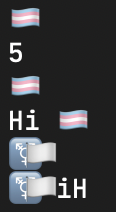
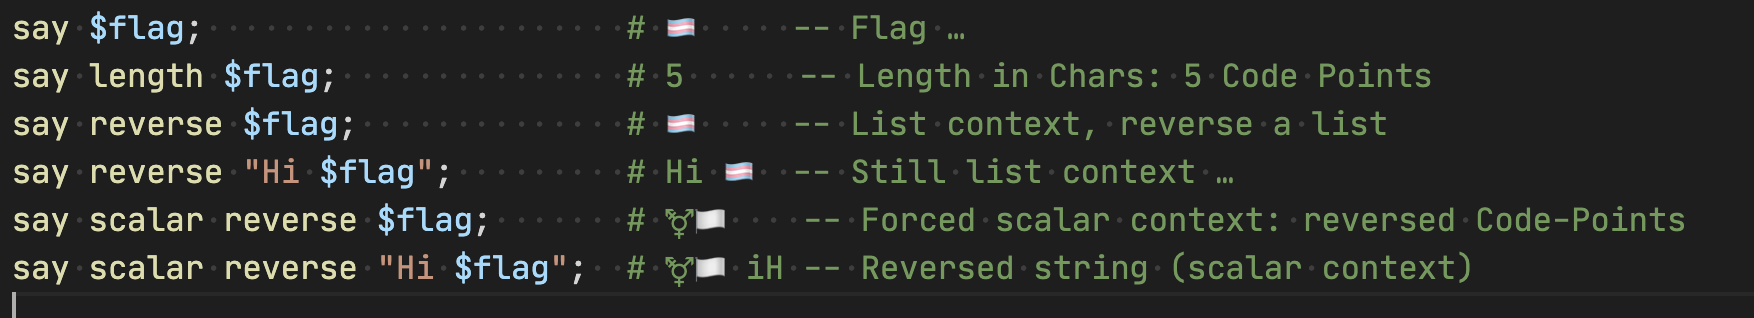
alvar@freude.social@fluepke Well… once you know how to do it, it all makes perfect sense… 🤡
 1
0
0
Flüpke
fluepke@chaos.social@alvar I always thought, Perl is famously known for being very good at text manipulation …
For me, a programming languages' string representation and APIs have always been a good litmus test for the quality of the language's design.
Some languages get the edge cases remarkably right. Rust, for example, understands that a filesystem path isn't necessarily a Unicode string and gives it its own type.
And then, there's Python 2.7 or Java. Or PHP even.
0
0
1
[4FBB09]
5225225@furry.engineer@thias @fluepke because you know that "the string you're interested in" is &string[500..600] (as in, you did a regex match or something and got back the start,end, and now you can use that to index into the string).
and it doesn't pretend to be useful in isolation the way unicode scalar value indexing does (you can write code that is "correct" up until you write 🏳️⚧️ or any other multi-codepoint emoji)
0
0
0
kris from the hit game deltarune
goes2hard@labyrinth.zone
1
0
0
[4FBB09]
5225225@furry.engineer@goes2hard @fluepke (omg kris hi)
yeah. indexing by that is really expensive (since it's basically a linear scan) but you can definitely iterate over bytes/codepoints/USVs
swift does something like this (and it means their "char" has to basically be a straight up string, see https://developer.apple.com/documentation/swift/character )
1
0
0
[4FBB09]
5225225@furry.engineer@goes2hard @fluepke uhhhh that works, yeah, though at the cost of memory(you need to store an index for everything you might want to index by) and it makes mutation hard
ultimately a lot of use cases for string processing don't actually need indexing, they need iteration, and iteration can be done cheaply without a precomputed index
0
0
0
Graham Sutherland🎃 / Polynomial.pdf.exe
gsuberland@chaos.social@fluepke Japanese characters can be written in wide or narrow form, which have different Unicode encodings. the width depends on the device you're typing on, with narrow being common as a default on mobile soft-keyboards and wide being the typical default when writing on a desktop keyboard. as such, passwords written in CJK scripts may encode to different byte sequences depending on whether the user logs in via mobile or desktop, and therefore produce different hashes/keys.
1
0
1
Graham Sutherland🎃 / Polynomial.pdf.exe
gsuberland@chaos.social@fluepke you have to run NFC normalisation over the string first to get a consistent byte sequence.
however! this is not actually sufficient on its own. another gotcha is that the normalisation result depends on the Unicode version. for long term stability (e.g. if you're using the password as an input to a KDF for bulk storage encryption) you need to pin the Unicode version alongside the hash. failing to do so many result in a user no longer being able to recover data.
1
0
0
Graham Sutherland🎃 / Polynomial.pdf.exe
gsuberland@chaos.social@fluepke and since a new user password might contain grapheme clusters that only exist in newer Unicode versions, you either need to have a version upgrade path (no global version pin) or reject any password that contains an unrecognised cluster.
this is even more difficult if you're doing any kind of client-side / server-side agreement, especially across distinct platform and language stacks, because both sides need to be on the same Unicode version and be doing the same normalisation.
1
0
0
Graham Sutherland🎃 / Polynomial.pdf.exe
gsuberland@chaos.social@fluepke also: if your threat model includes timing attacks, you need to do the Unicode cluster validity checks and NFC normalisation in constant time.
1
0
0
Graham Sutherland🎃 / Polynomial.pdf.exe
gsuberland@chaos.social@fluepke also also: if you're doing any kind of nonrepudiation of string equality where malicious modification is in scope you also need to authenticate the Unicode version that was used, e.g. in the AD portion of an AEAD.
0
0
0
sodiboo 
sodiboo@gaysex.cloud
@fluepke the noun phrase “Unicode code point” in this meme should be replaced with “Unicode scalar value”.
the surrogate pairs are two code points which encode a single scalar value. and although it is most correct to say the UTF-16 string contains 6 code units, it is also valid to say it contains 6 code points; whereas the same string in UTF-8 definitely only contains 5 code points. both, however, unambiguously contain exactly 5 scalar values (not counting the BOM or the NUL, which are depicted in the encoding and are both scalars, but they’re definitely not part of the 🏳️⚧️) (and yes, a scalar value is a code point, so the UTF-16 🏳️⚧️ contains both 5 and 6 code points at the exact same time, which is exactly why i think the meme shouldn’t use this term)
0
0
0
sodiboo
sodiboo@gaysex.cloud
@charlotte @fluepke @5225225 i think that by ANY sensible definition of character that any programmer can ever make sense of, ﷽ cannot possibly be more than one character, because it is NFC, NFD, NFKC, and NFKD, of itself.
however, “ä” could reasonably be considered multiple characters programmatically, even though it is a single codepoint, its NFD and NFKD aren’t
0
0
0