
Posts
1610Following
HiddenFollowers
Hidden
 repeated
Charlotte  /Cinny

charlotte

I’m in IC 3580 towards Eindhoven Centraal! #NowTräwelling
https://traewelling.de/status/4110388
 0
1
 1
repeated

Chris Trottier
atomicpoet@atomicpoet.orgSpotify has been caught red-handed, though they deny it.
They claim it isn’t happening, but reports suggest they’re hiring contractors to create fake artists to pad playlists. Increasingly, the music on Spotify isn’t made by genuine artists—people earnestly trying to make a living in the music industry. Instead, it’s generated by Spotify itself.
Most listeners don’t care. They’re just looking for a mood, a soundtrack to fill their day. They don’t think about who creates the music or what it represents. But at some point, we need to ask ourselves: are we okay supporting this predatory behavior? Sadly, I doubt most people care.
It makes me wonder—when did we, as a society, stop caring about others’ well-being? About whether someone can earn a living doing what they love? We’ve been indoctrinated by capitalism’s survival-of-the-fittest mindset: claim your spot, or someone will take it. But I can’t help feeling disheartened.
I listen to a lot of music and feel connected to the artists. My home is filled with art—paintings, books, vinyl records. When I hear a song, I like to think it tells a story, revealing something about the people who created it. Yet everything feels increasingly artificial.
This isn’t new. Growing up, I knew MTV wasn’t about real music—it sold a lifestyle. The faces in the music videos weren’t living a glamorous life. I met artists who told me touring for 200 days a year was brutal. We worship the glamour, but imagine waking up on a freezing tour bus, miserable. Now, Spotify makes it even harder for musicians to make a living.
Musicians today assume they’ll make next to nothing from recordings. Their songs are now free-to-consume marketing for tours. But even touring is grueling and unpredictable. It’s heartbreaking to see talented people unable to survive on their craft.
I’ve tried to make a living from art. I’ve created, shared, and hoped to connect with others. But the way social media works reduces everything to “content”—just fuel for the algorithm. Your art becomes a commodity, stripped of its humanity, fed into a larger, faceless machine.
This is the world we’re building: Spotifys, YouTubes, TikToks, Facebooks. Does anyone care? They should. We need to reclaim what’s ours—not just as creators but as consumers. We need to care about where our attention goes and what we support.
With platforms growing greedier, controlling what we see and hear, we need to push back. Some argue that removing the old gatekeepers is what caused this mess. But did we really get rid of them? Or did we just trade them for even worse ones? And if so, how do we break down those new walls?
https://harpers.org/archive/2025/01/the-ghosts-in-the-machine-liz-pelly-spotify-musicians/
0
4
0
repeated
Charlotte /Cinny
charlotte
time spent fursuiting in a calendar year:
2025: 100%
we’re going strong
1
1
6
 repeated

𝚃𝚊𝚛𝚊𝚜 𝙶𝚛𝚎𝚜𝚌𝚘𝚎 🚇
straphanger@urbanists.socialShow content
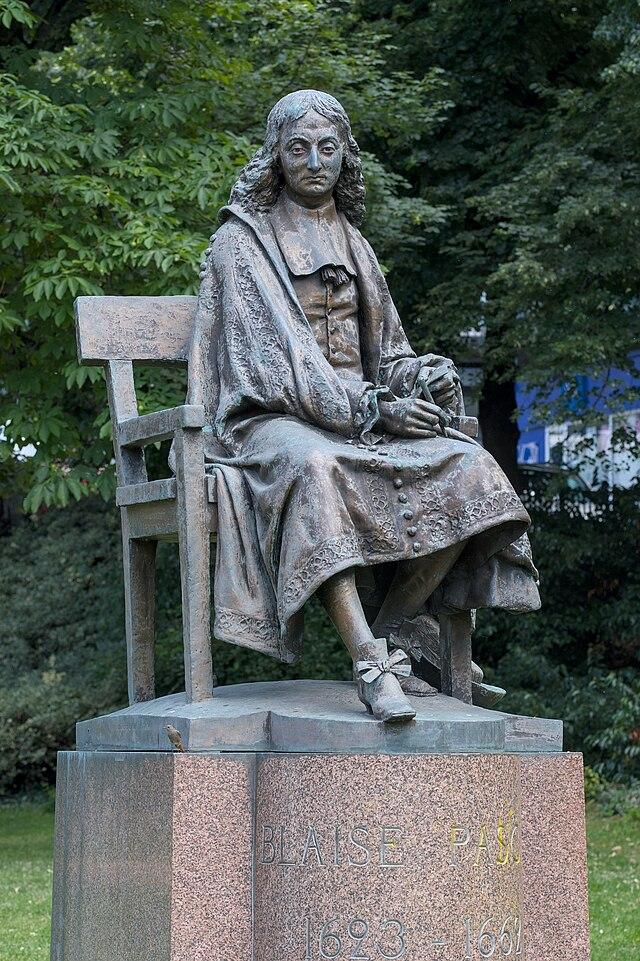
In the 1660s, this French philosopher came up with an invention that solved the problem of urban transport forever.
It had nothing to do with Robo-taxis, flying cars, or Tesla Tunnels.
🧵
 1
3
0
repeated
recovering (give time) 🦊🇰🇿
mynameistillian@plush.city
i regret to inform you daily mail found out about vore
4
5
1
repeated

Nall 
nall@dook.business
We call it Foxing Day because in late prehistory, about 7000 years ago, our ancestors spiced their drinking water to create the first foxkin. They experimented on themselves to make us.
Why? Our best guess is that a microculture did this, although we don't know exactly why; there are theories.
Was it right? That's a big question. The ethics of their actions are beyond the scope of this course, but if you do stay on another year, we'll talk all about it. 🦊
0
3
0
repeated
ptrc: gelderland arc
ptrc@treehouse.systemshot take: web browsers replacing desktop apps is a failure on the side of GUI toolkits
7
2
0
repeated
 repeated
Misty
misty@digipres.clubIt’s hard to overemphasize just what a bombshell this was for the webcomic scene in the late 90s/early 00s. Comics had been using GIF even for non-animated strips, and major comics started spearheading anti-GIF campaigns and teaching people how to switch to PNG.
https://ioc.exchange/@siliconundergro/113708037589718726
1
4
0
miifox
miifox
0
0
0
repeated

StevenSavage (he/him)
StevenSavage@sfba.socialPresident Musk tells people not to donate to Wikipedia.
So send them money.
https://www.newsweek.com/elon-musk-takes-aim-wikipedia-fund-raising-editing-political-woke-2005742
38
3
0
repeated
Charlotte /Cinny
charlotte
the only good ad is the kind that provides unintended irony
tv ad for or ISP. right at the end of the advertisement the tv disconnects from the internet and the picture freezes on “Telekom: Connecting the World”
0
1
2
repeated
Charlotte /Cinny
charlotte
remember to regularly update the name of your first dog for security reasons!
2
23
51
repeated
Charlotte /Cinny
charlotte
Show content
trying to show my gf the city but nazi protests get into way which pigs allowed them to instrumentalize their own terrorist attack like this
0
1
4
repeated
Alice Averlong🏳️⚧️
foone@digipres.clubTechnically, if you're not watching YouTube on a CRT, there's no tube.
It's just sparkling Google Video.
4
1
0
repeated
Osmose
Osmose@digipres.clubThe thing about copyright is, like, if you just think about it for a moment, these two situations are completely different:
- Sony releases a game with music it downloaded off SoundCloud without ever contacting the musician
- A high schooler makes a Sonic fan game that reuses music from Sonic Adventure 2
And yet our current conception of copyright insists that these are equivalent and should be handled by the same rules.
Even if you think copyright should exist this form of it is nonsense.
0
2
0
repeated

David Chisnall (*Now with 50% more sarcasm!*)
david_chisnall@infosec.exchangeI finally turned off GitHub Copilot yesterday. I’ve been using it for about a year on the ‘free for open-source maintainers’ tier. I was skeptical but didn’t want to dismiss it without a fair trial.
It has cost me more time than it has saved. It lets me type faster, which has been useful when writing tests where I’m testing a variety of permutations of an API to check error handling for all of the conditions.
I can recall three places where it has introduced bugs that took me more time to to debug than the total time saving:
The first was something that initially impressed me. I pasted the prose description of how to communicate with an Ethernet MAC into a comment and then wrote some method prototypes. It autocompleted the bodies. All very plausible looking. Only it managed to flip a bit in the MDIO read and write register commands. MDIO is basically a multiplexing system. You have two device registers exposed, one sets the command (read or write a specific internal register) and the other is the value. It got the read and write the wrong way around, so when I thought I was writing a value, I was actually reading. When I thought I was reading, I was actually seeing the value in the last register I thought I had written. It took two of us over a day to debug this. The fix was simple, but the bug was in the middle of correct-looking code. If I’d manually transcribed the command from the data sheet, I would not have got this wrong because I’d have triple checked it.
Another case it had inverted the condition in an if statement inside an error-handling path. The error handling was a rare case and was asymmetric. Hitting the if case when you wanted the else case was okay but the converse was not. Lots of debugging. I learned from this to read the generated code more carefully, but that increased cognitive load and eliminated most of the benefit. Typing code is not the bottleneck and if I have to think about what I want and then read carefully to check it really is what I want, I am slower.
Most recently, I was writing a simple binary search and insertion-deletion operations for a sorted array. I assumed that this was something that had hundreds of examples in the training data and so would be fine. It had all sorts of corner-case bugs. I eventually gave up fixing them and rewrote the code from scratch.
Last week I did some work on a remote machine where I hadn’t set up Copilot and I felt much more productive. Autocomplete was either correct or not present, so I was spending more time thinking about what to write. I don’t entirely trust this kind of subjective judgement, but it was a data point. Around the same time I wrote some code without clangd set up and that really hurt. It turns out I really rely on AST-aware completion to explore APIs. I had to look up more things in the documentation. Copilot was never good for this because it would just bullshit APIs, so something showing up in autocomplete didn’t mean it was real. This would be improved by using a feedback system to require autocomplete outputs to type check, but then they would take much longer to create (probably at least a 10x increase in LLM compute time) and wouldn’t complete fragments, so I don’t see a good path to being able to do this without tight coupling to the LSP server and possibly not even then.
Yesterday I was writing bits of the CHERIoT Programmers’ Guide and it kept autocompleting text in a different writing style, some of which was obviously plagiarised (when I’m describing precisely how to implement a specific, and not very common, lock type with a futex and the autocomplete is a paragraph of text with a lot of detail, I’m confident you don’t have more than one or two examples of that in the training set). It was distracting and annoying. I wrote much faster after turning it off.
So, after giving it a fair try, I have concluded that it is both a net decrease in productivity and probably an increase in legal liability.
Discussions I am not interested in having:
- You are holding it wrong. Using Copilot with this magic config setting / prompt tweak makes it better. At its absolute best, it was a small productivity increase, if it needs more effort to use, that will be offset.
- This other LLM is much better. I don’t care. The costs of the bullshitting far outweighed the benefits when it worked, to be better it would have to not bullshit, and that’s not something LLMs can do.
- It’s great for boilerplate! No. APIs that require every user to write the same code are broken. Fix them, don’t fill the world with more code using them that will need fixing when the APIs change.
- Don’t use LLMs for autocomplete, use them for dialogues about the code. Tried that. It’s worse than a rubber duck, which at least knows to stay silent when it doesn’t know what it’s talking about.
The one place Copilot was vaguely useful was hinting at missing abstractions (if it can autocomplete big chunks then my APIs required too much boilerplate and needed better abstractions). The place I thought it might be useful was spotting inconsistent API names and parameter orders but it was actually very bad at this (presumably because of the way it tokenises identifiers?). With a load of examples with consistent names, it would suggest things that didn't match the convention. After using three APIs that all passed the same parameters in the same order, it would suggest flipping the order for the fourth.
21
15
1